Motivation for reading / Who should read this:
I read Validity and Validation – Understanding Statistics, by Catherine S. Taylor in part as a follow up to the meta-analysis book from two weeks ago, and in part because I wanted to know more about the process of validating a scale made from a series of questions (e.g. The Beck Depression Inventory, or a questionnaire about learning preferences). For scale validation, there’s a field called Item Response Theory, which I understand better because of this book, but not at any depth.
This book, a quick read at 200 small pages, compliments the handbook of educational research design that Greg Hum and I made. I plan to recommend it anyone new to conducting social science research because it provides a solid first look at the sort of issues that can prevent justifiable inferences (called “threats to internal validity”), and those that can limit the scope of the results (called “threats to external validity”).
A good pairing with “Validity and Validation” is “How to Ask Survey Questions” by Ardene Fink. My findings from that book are in this post from last year. If I were to give reading homework to consulting clients, I would frequently assign both of these books.
What I learned:
Some new vocabulary and keywords.
For investigating causality, there is a qualitative analogue to directed acyclic graphs (DAGs), called ‘nomological networks’. Nomological networks are graphs describing factors, directly or not, that contribute to a construct. A construct is like a qualitative analogue of a response variable, but has a more inclusive definition.
To paraphrase of Chapter 1 of [1], beyond statistical checks that scores from a questionnaire or test accurately measure a construct, it’s still necessary to ensure the relevance and utility of that construct.
Hierarchical linear models (HLMs) resemble random effect models, or a model that uses Bayesian hyperpriors. An HLM is a linear model where the regression coefficients are themselves response values to their own linear models, possibly with random effects. More than two layers are possible, in which the coefficients in each of those models could also be responses to their own models, hence the term ‘hierarchical’.
What is Item Response Theory?
Item response theory (IRT) is set of methods that puts both questions/items and respondents/examinees in the same or related parameter spaces.
The simplest model is a 1-Parameter IRT model, also called a Rasch model. A Rasch model assigns a ‘difficulty’ or ‘location’ for an item based on how many respondents give a correct/high answer or an incorrect/low answer. At the same time, respondents also have a location value based on the items they give a correct/high response. An item that few people get correct will have a high location value, and a person that gets many items correct will have a high location value.
A 2-parameter model includes a dimension for ‘discrimination’. Items with higher discrimination will elicit a greater difference in responses between respondents with a lower and those with a higher location than the item. Models with more parameters and ones for non-binary questions also exist.
The WINSTEPS software package for item response theory (IRT):
WINSTEPS is a program that, when used on a data set of n cases giving numerical responses each of to p items, gives an assessment of how well each item fits in with the rest of the questionnaire. It gives two statistics: INFIT and OUTFIT. OUTFIT is like a goodness-of-fit measure for extreme respondents at the tail-ends of dataset. INFIT is a goodness-of-fit measure for typical respondents.
In the language of IRT, this means INFIT is sensitive to odd patterns from respondents whose locations are near that of the item, and OUTFIT is sensitive to odd patterns from respondents with locations far from the item. Here is a page with the computations behind each statistic.
On CRAN there is a package called Rwinsteps, which allows you to call functions in the WINSTEPS program inside R. There are many item response theory packages in R, but the more general ones appear to be “cacIRT”, “classify”, “emIRT”, “irtoys”, “irtProb”, “lordif”, “mcIRT”, “mirt”, “MLCIRTwithin”, “pcIRT”, and “sirt”.
For future reference.
Page 11 has a list of common threats to internal validity.
Pages 91-95 have a table of possible validity claims (e.g. “Scores can be used to make inferences”), which are broken down into specific arguments (e.g. “Scoring rules are applied consistently”), which in turn are broken down into tests of that argument (e.g. “Check conversion of ratings to score”).
Pages 158-160 have a table of guidelines for making surveys translatable between cultures. These are taken from a document of guidelines of translating and adapting tests between languages and cultures from the International Test Commission. https://www.intestcom.org/files/guideline_test_adaptation.pdf
The last chapter is entirely suggestions for future reading. The following references stood out:
[1] (Book) Educational Measurement, 4th edition, by Brennan 2006. Especially the first chapter, by Messick
[2] (Book) Hierarchical Linear Models: Applications and Data Analysis by Ravdenbush and Bryk 2002.
[3] (Book) Structural Equation Modelling with EQS by Byrne 2006. (EQS is a software package)
[4] (Book) Fundamentals of Item Response Theory, by Hambleton, Swaminthan, and Rogers 1991.
[5] (Book) Experimental and Quasi-Experimental Designs for General Causal Interance by Shadish, Cook, and Campbell 2002. (this is probably different from the ANOVA/Factorial heavy Design/Analysis of Experiments taught in undergrad stats)
[6] (Journal) New Directions in Evaluation
Sunday, 29 November 2015

Tuesday, 10 November 2015
I read this: Meta-Analysis, A Comparison of Approaches
My motivation for reading Meta-Analysis: A Comparison of Approaches by Ralph Schulze was to further explore the idea of a journal of replication and verification. Meta-analyses seemed like a close analogy, except that researchers are evaluating many studies together, rather than one in detail. I’m not working on any meta-analyses right now, but I may later. If you are reading this to decide if this book is right for you, consider that your motivations will differ.
Saturday, 31 October 2015
A Web Crawler using R
This R-based web crawler, available here...
1. Reads the HTML of a webpage from a given address,
2. Extracts the hyperlinks from that page to other pages and files,
3. Filters out links that fail to meet given criteria (e.g. other websites, already explored, and non-html)
4. Stores the origin and destinations of the remaining links,
5. Selects a link from those discovered so far, and returns to 1.
The scraper can be used to gather raw data from thousands of pages from a website, and reveal information of the network of links between them. For example, starting just now at the front page of the National Post website, the crawler visited a news article, the main page for horoscopes, the day's horoscopes, and an article from the financial pages of the paper.
Wednesday, 28 October 2015
Take-home lessons and code from a factor-cluster analysis with imputation
Recently I was tapped to examine data from a survey of ~200 children to find if their learning preferences fell into well-defined profiles (i.e. clusters). The relevant part of the survey had more than 50 Likert scale questions The client and I had decided that a factor analysis, followed by a cluster analysis would be most appropriate.
I learned some things in doing this analysis, and wanted to share that and some relevant code.
Sunday, 18 October 2015
Teaching Philosophy Statement on Intro Math/Stats - Cartographers of Knowledge
In the digital age, a teacher's role is not simply to present knowledge, but to navigate it. The overwhelming majority of the information that an undergraduate gains in her degree is available for free on the internet or in libraries.
A digital age instructor's job is to guide and motivate students' paths through this information – to provide the vision and context necessary to develop expertise in a field. Introductory courses make up the bulk of students' collective experience with mathematics and statistics, so any expertise to be gained in those one or two courses needs to be a self-contained package.
For example, rigorous proofs serve introductory students very little; the practice of rigor and constructing proofs has little value until upper-division courses. Introductory students learn by doing the tasks that are actually relevant to the course: examples. As such, I prefer to relegate much of the proof work to optional out-of-class readings. The extra instructional time for guided, step-by-step examples makes the material more accessible. It also provides more opportunities to fill the fundamental gaps from high school mathematics that will otherwise prevent understanding. For the few that do continue in a mathematics or statistics major, I feel that what they may lack in experience with proofs is more than compensated by a stronger foundation in the introductory material.
This focus on accessibility extends to my policies on assignments and office hours. Assignments should be vehicles for students to struggle through a set of practice problems and receive formative feedback. However, logistics of providing quality feedback aside, that doesn't work for everyone. Assignments need to have grades attached so students will have extrinsic motivation to completing them, but these same grades penalize mistakes on something that should be practice.
I want assignments to be important and challenging enough to take seriously, but not so much as to tempt plagiarism. In the past, I have solved this by booking extra office hours on the days before assignments are due, and telling my students that I will give them entire solutions to assignment questions. I've found that on these office days, a group of 5-12 students would come to my office with their assignment hang-ups, but that they could answer each others' questions with only moderate guidance from me. Some of these students likely sat in to get their solutions from the rest of the office group, but that's still better than copying written assignments verbatim.
Finally, I try to explicitly declare the 'take-home messages' by including them in my lessons. That is, the few ideas that I hope students will remember long after the final exam is over. These messages include general strategies about the mathematical sciences such as “every hard problem is merely a collection of easy problems”, and George Box's quote “all models are wrong, some are useful.”. If my students are to retain anything from their time spent on coursework, I hope it's something of value and general applicability rather than memories of referring to tables of integrals and probability.
Monday, 12 October 2015
Now you're thinking with gates!
What do Nintendo and Bitcoin enthusiasts have in common? They weren't content with solving their problems through software advancements alone. The statistical computing field shouldn't be either.
-------------------
The Super Nintendo Entertainment System is a cartridge-based system, meaning that its games were stored on circuit boards encased in plastic cartridges. Unlike disc-based media of most later generations of game consoles, the contents of cartridges were not restricted to read-only data. The most common addition to game cartridges was a small cache of re-writable memory used to store progress data in the cartridge.
Originally, active objects in games, called sprites, could only be displayed as one of a set of pre-drawn frames. That's why sprite animations are usually simple loops of a few frames, and why characters are rarely seen changing size as they move towards or away from the player's point of view.
However, later games also included special-purpose microchips that expanded the graphical capabilities of the Super Nintendo console itself. One of these chips allowed the SNES to change the way sprites look as the game was happening, which made sprites look much more alive. This chip also allowed for rudimentary three-dimensional rendering.
Any software workaround to get these effects using only the hardware given in the Super Nintendo would have taking much longer and produced much worse results, if any at all. The video on the Super Nintendo (SNES) by video game trivia group Did You Know Gaming covers these effects and the chips in more detail, and shows some great demonstrations.
------------------
Bitcoin, is a cryptocurrency. Part of what gives it value is the premise that it is computationally hard to create or 'mine' for new ones. In fact, there is a self-adjustment mechanism that increases the mining difficulty in proportion to the total computing power of all miners.
I've appended this historical chart of the log of the total computer power (and the log difficulty), over time with the two hardware advancements that defined the trend in bitcoin mining power.
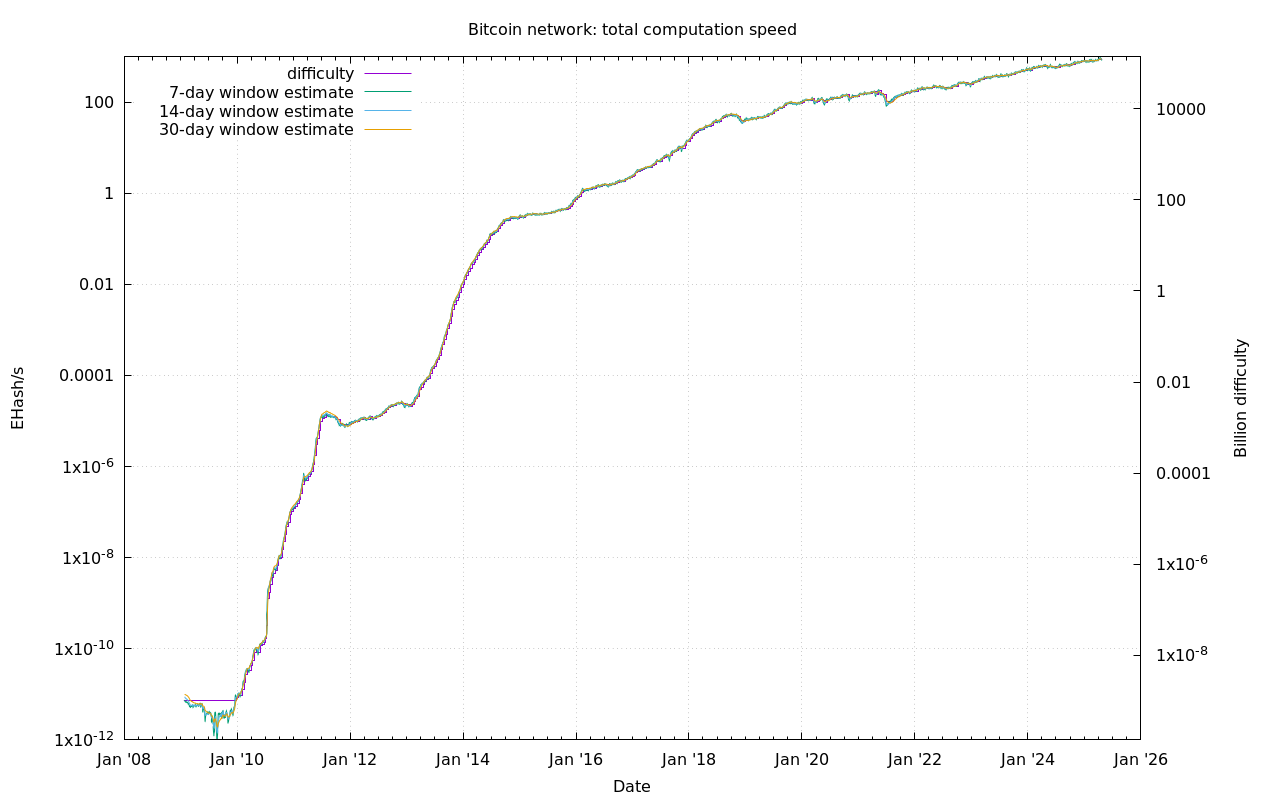

The first event represents the first time mining using a more specialized graphical processing unit (GPU) rather than a more general central processing unit (CPU) was made publicly possible. Since many miners had compatible graphics cards already, we see a tenfold jump in power almost instantly.
The second event represents the first time mining using a single-purpose processor, called an ASIC* was introduced to the market. This time, another rapid increase in processing power is sparked, but without the initial leap.
An ASIC is orders of magnitude faster at the simple, repetitive task of mining bitcoins than a GPU is, and a GPU mines orders of magnitude faster than a comparably priced CPU. In both cases, the new hardware quickly rendered any previous mining methods obsolete.
* Application Specific Integrated Circuit.
---------------
When developing new methods to solve computational problems, a software approach usually works best. The results of purely software-based are often portable as packaged programs, and the dissemination of improvements can be as quick and as cheap as a software update. The feedback loop of testing and improvement is very quick, and there are many languages such as the R, SAS, and Julia that can make software-based solutions a routine task.
Making hardware to solve a problem may sound insane by comparison - why would anyone willingly give up all of those advantages? This is where Field Programmable Gate Arrays come in. An FPGA is essentially a circuit board that can be programmed down to the gate level. That is, a user can write a program in terms of the fundamental particles of computation, OR, NOT, XOR, AND, and NAND gates.
The FPGA takes a set of gate instructions and physically wires itself into the programmed configuration. When set, the FPGA is essentially an ASIC, an processor that can only do one task but potentially much faster than a general purpose computer. However, if needed, an FPGA can be re-programmed, so the advantage of a quick trial-and-error turnaround is there. Also, the program can be disseminated like any other software. The most popular FPGAs cost between $200 and $500 USD.
The bitcoin ASIC started off as an FPGA. Once the FPGA program was made, it took about a year for the first ASICs to be sold. This is encouraging for anyone looking towards FPGAs for the next great leap in statistical computing, as it means the endeavor has commercial viability. Just think how much faster some common methods could become even if only large matrix inversion was made faster.
It's time to start thinking with gates.
Tuesday, 8 September 2015
Arguments for Journals of Replication
In today's xkcd, a collection of hypothetical headlines are given, all of which would spell trouble for science as a whole. Also, these headlines all have to do with replicating experiments. The only fictional part of (most of) these headlines is that they're showing up in the news, because this is an old problem. Given that new journals are frequently being made as fields evolve and grow, it's surprising to not find any journals of replication and verification, because having such journals could help make science more honest.
Creating and contributing to journals dedicated to replicating, verifying, and assessing work in a field is a worthwhile endeavour. Here's why:
Primary Motivation - Having a journal of replication in a field would implicitly improve the quality of research across that field. It would do this by effectively putting a bounty on bad research by offering a publication opportunity for addressing flaws. It also provides an incentive for a team that 'gets there second' to publish, which could remove some of the unscientific competitiveness of people working towards the same goal. Finally, it provides relatively easy publication opportunities for people wishing to do the work that makes a field's body of work more cohesive by repeating key experiments or by conducting meta-studies.
Assertion 1 - Replication has high scientific value: Consider an experiment done twice, in two independent labs. It may not produce as much new information as two different experiments, but the information it does provide would be of a higher quality. That's what scientific journals are supposed to do - focus on quality. Large volumes of low quality information can be found anywhere.
Assertion 2 - Replication is easy and safe: Assuming that the method have been outlined well, someone trying to replicate an experiment can skip past a lot of the planning and false starts of the original researcher. The second research team even has the first one to ask questions. It's safe in that the chance of a new discovery, and hence publication delays, is low. This makes it suitable for the sort of mass produced work that can be outsourced to graduate students with minimal degree hiccups.
Assertion 3 - A replication journal has reward potential for contributors: Logically, most replication papers fall into two categories: Refutation or verification. If research is verified, the original researchers gain prestige and a citation, and the replicators gain a publication. In future work, many groups mentioning the original work will want to cite both papers because together they make a stronger argument. If the research if refuted, at best it could spark interest in 'tiebreaker' work by a 3rd research party, which would cite both (positively, if everything was done honestly), and at worst the original work dies early where it would or should have anyway, and the replicators establish their reputation for rigor.
Assertion 4 - A replication journal has reader appeal: If someone is reading a research paper, they may be interested how credible the work is after it has been subject to public scrutiny. A replication journal appropriate to the paper's field would be a good first place to look because it would save the reader the trouble of filtering through work that cited the paper in question or looking for otherwise related work that may lend to or take credence from the paper. In short, a replication journal would offer the same service to readers that review sites offer to consumers of more commercial goods.
Assertion 5 - A replication journal would be easy to administer: Aside from papers on related verification methods, all the relevant submissions to such a journal would be adhere to specific formulae - they would either be direct replications or metastudies. Hopefully, this would make the editing and review work of these papers easier because most viable papers would look the same: Introduction of the work to be replicated, comparison of methods, comparison of results, short discussion. Criteria for publication would have few ambiguities that require editorial decision-making.
Subscribe to:
Posts (Atom)