Featured post

Textbook: Writing for Statistics and Data Science

If you are looking for my textbook Writing for Statistics and Data Science here it is for free in the Open Educational Resource Commons. Wri...

Wednesday, 6 December 2017

Reflection on teaching a 400-level course on Big Data for statisticians.

This was the first course I have taught that I would consider a 'main track' course, in that the students were to learn more about what they were already competent in at the start. Most of the courses I have previously taught were 'service courses', in that they were designed and delivered by the Statistics Department in service to other departments that wanted their own students to have a stronger quantitative and experimental background (e.g. Stat 201, 203, 302, and 305). The exception, Stat 342, was designed for statistics majors, but is built as an introduction to SAS programming. Since most other courses in the program are taught using R or Python, teaching SAS feels like teaching a service course as well, in that I am teaching something away from the students' main competency, and enrollment is mainly driven by requirement rather than interest.

In my usual courses, I am frequently grilled from anxious students about what exactly is going to be on exams. Frequent complaints I receive in student responses are about how I spend too much time on 'for interest' things are not explicitly being tested on the exams. I've also found that I needed to adhere to rigid structure in course planning and in grading policy. Moving an assignment's due date, teaching something out of the stated syllabus order, changing the scope or schedule of a midterm, or even dropping an assignment and moving the grade weight have all caused a cascade of problems in previous classes.

Stat 440, Learning from Big Data, was a major shift.

I don't know which I prefer, and I don't know which is easier in the long term, but it is absolutely a different skill set. The bulk of the effort changed from managing people to managing content. I did not struggle to keep the classroom full, but I did struggle to meaningfully fill the classroom's time. I had planned to cover the principles of modern methods (cross validation, model selection, LASSO, dimension reduction, regression trees, neural nets), some data cleaning (missing data, imputation, image processing), some technology (SQL, parallelization, Hadoop), some text analysis (regular expressions, edit distance, XML processing), but I still had a couple of weeks that I had to fill at the end because of the lightning speed that I was able to burn through these topics without protest.


In 'big data', the limits of my own knowledge became a major factor. Most of what I covered in class wouldn't have been considered undergrad material ten years ago when I was a senior (imputation, LASSO, neural nets); some of it didn't exist (Hadoop). There are plenty of textbook and online resources for learning regression or ANOVA, but the information for many of the topics of this course were cobbled together from blog posts, technical reports, and research papers. A lot of resources were either extremely narrow in scope or vague to the point of uselessness. I needed materials that were high-level enough for someone not already a specialist to understand, and technical enough that someone well-versed in data science would get something of value from it, and I didn't find enough.

The flip side of this was that motivation was easy. Two of the three case studies assigned had an active competition component to them. The first such study was a US-based based challenge to use police data from three US cities. In this one, presentation was a major basis that the police departments would judge the results. As such, I had requests for help with plotting and geographic methods that were completely new to me. A similar thing happened with the 'iceberg' case study, based on this Kaggle competition. I taught the basics of neural nets, and at least three groups asked me about generalizations and modifications to neural nets that I didn't know about. (The other case study was a 'warm-up' in which I adapted material from a case study competition held by the Statistical Society of Canada. The students were not in active competition). At least 20% of the class has more statistical talent than I do.

In order to adapt to this challenge and advantage, I changed about mid-semester from my usual delivery method of a PDF slideshow to one of commentary while running through computer code. This worked well for material that would be directly useful for the three case study projects, such as all the image processing work I showed for the case study on determining the difference between icebergs and ships. It wasn't as good for material that would be studied for the final exam. I went through some sample programs on web scraping, and the feedback wasn't as positive for that, and the answers I got on the final exam for the web scraping question were too specific to the examples I had given.

A side challenge was the ethical dilemma of limiting my advice to students looking to improve their projects. I had to avoid using insights that other students had shared with me because of the competitive nature of the class. Normally if someone had difficulty with a homework problem, I could use their learning and share it with others, but this time, that wasn't automatically the case.

There was also a substantial size difference, I had 20-30 students, which is by far the smallest class I've ever lectured to. Previously, Stat 342 was my 'small' class, which had enrollment between 50-80, because it was compared to service classes of 100-300 students. This allowed me to actually communicate with students an a much more one-on-one level. Furthermore, since most of the work was done in small team settings, I got to know what each group of students was working on for their projects.

I worry that what I delivered wasn't exactly big data, and was really more of a mixed bag of data science. However, there was a lot of feedback from the students that they found it valuable, and value-added was what the goal all along.

Monday, 13 November 2017

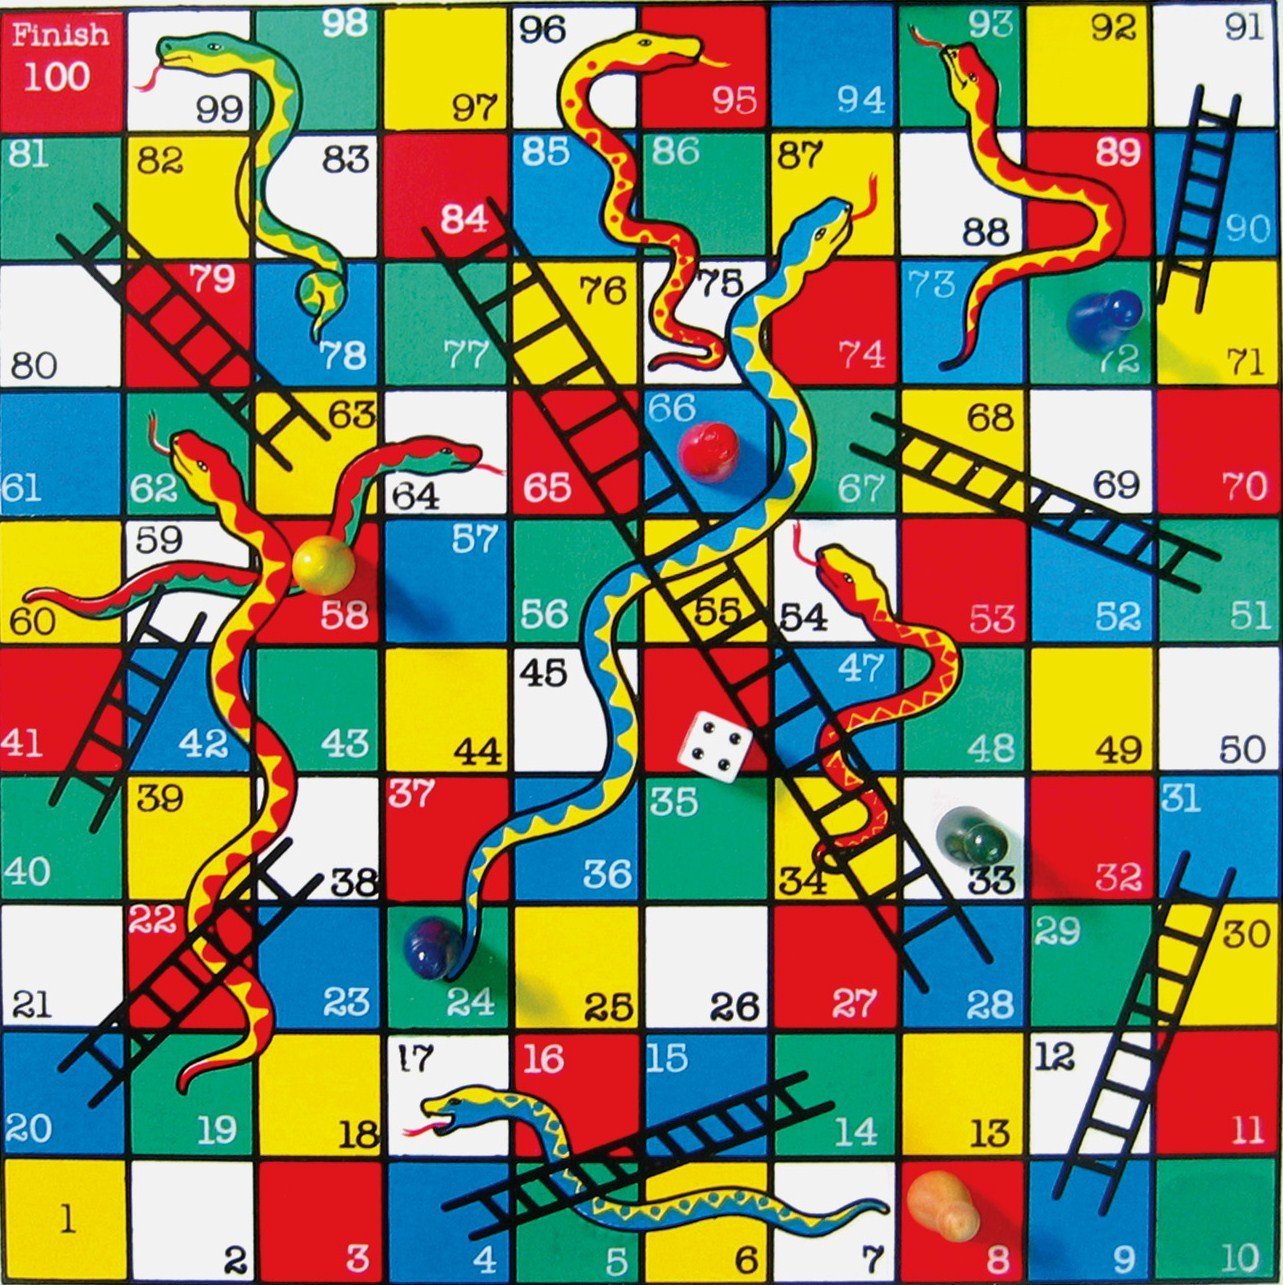
Snakes and Ladders and Transition Matrices

Recently, /u/mikeeg555 created this post  on the statistics subreddit with their results from a simulation of 10,000,000 games of this instance of Snakes and Ladders. This is the sort of information that's good to show in an undergrad or senior secondary level classroom as a highlight of the sort of insights you can get from the kind of simulation that anyone can program.

Wednesday, 8 November 2017

Writing a Resume as a Data Scientist or Statistician.

What do viral posts and resumes have in common? They rise to the top based on a very superficial evaluation.

Here are some notes from a seminar on resume writing for students, especially undergraduates, in statistics and data science.


Thursday, 2 November 2017

Evaluating Exam Questions using Crowdmark, IRT, and the Generalized Partial Credit Model

Making good exam questions is universally hard. The ideal question should have a clear solution to those with the requisite understanding, but also difficult enough that someone without the knowledge needed can guess at an answer.

An item response theory (IRT) based analysis can estimate the difficulty of a question, as well as the general skill of each of the test takers. The generalized partial credit model extends classical IRT from questions with binary scores to ones with an ordinal set of possible scores.

R code and example inside.

Tuesday, 3 October 2017

Book review of Improving How Universities Teach Science Part 2: Criticisms and comparison to the ISTLD


As far as pedagogical literature goes, Carl Wieman’s Improving How Universities Teach Science - Lessons from the Science Education Initiative was among my favourites. It keeps both jargon and length to a minimum, as it is barely more than 200 pages without counting the hiring guide at the end. The work and its presentation are strongly evidence-based and informative, and the transformation guide in the appendices provides possible actions that the reader can do to improve their own classes. Most of it is applicable to most of science education.

 I have some criticisms, but please don’t take this as a condemnation of the book or of the SEI in general.

The term ‘transformation’ is vague, despite being used extensively throughout the first two thirds of the book. This is partially forgivable because it has to be vague in order to cover what could be considered a transformation across many different science fields. However there could have been more examples or elaboration or a better definition of the term early on. First concrete examples to show up and clarify what transformation meant are found in the appendix, 170 pages in.

Dismissal of the UBC mathematics Department, and of mathematics education in general.

The metric Wyman used primarily the proportion of faculty that bought in to the program. That is the proportion of Faculty that transformed their courses, because typically faculty transformed all of their courses or none of them. Many departments were considered a success in that 70% or more of the faculty transformed their classes. Those that were under 50% were mostly special cases where they had entered into the Science Education initiative later and hadn't had the opportunity to transform. Among the All-Stars was the UBC statistics Department 88% of their 17 faculty with teaching appointments transform their classes. Among The Faculty of the UBC mathematics Department however only 10% of their 150 + strong Department bought in and transformed their classes. To contrast 1.2 million dollars was spent on the mathematics Department while $300,000 was spent on the statistics Department, so the mathematics people got more in total but the statistics people got more per faculty. It's not the failure to transform the mathematics Department that bothers me but the explanation for it.
Wieman boils down the failure to transform the mathematics department into two factors. First was the culture within that particular department, which was one that did not emphasize undergraduate education and seemed to assume that mathematics was an innate ability that either students had or had not regardless of the amount of effort put in. Before Wieman started attempting to transform this department it had a policy of automatically failing the bottom few percentiles of every introductory calculus class regardless of performance. The second factor Wieman uses to explain the failure is that mathematics is inherently not empirical, which means that a lot of the active learning meant to make Concepts more concrete would not have applied.

Having taught and been taught in both mathematics and statistics departments at multiple institutions myself I don't buy these arguments. From personal experience the most engaging and active classrooms I experienced have spread equally across mathematics and statistics. With in mathematics the most memorable was abstract algebra which by definition is non-empirical. Furthermore, at Simon Fraser University it's the mathematics department that has been leading the way on course transformation.
As for the argument about innate ability, this is an idea that spreads far beyond just university departments. I have no qualification to claim how true or false it is. However it's not a useful assumption, because it makes many things related to teaching quality in mathematics automatically non-actionable.
Finally it seems like a strange argument for a professor of physics to make about mathematics. I would have like to see more investigation and perhaps it's covered in some of his other literature, but then I would have like to see more reference towards that literature if it exists.

Compared to the Institute for the Study of Teaching and Learning in the Disciplines (ISTLD) at SFU, Wieman’s SEI is several times larger in scale and tackles the problem of university teaching entire departments at a time. The SEI works with department chairs directly and with faculty actively through their science education specialists. The ISTLD’s projects are self-contained course improvements, where staff and graduate student research assistants provided literature searches, initial guidance, and loose oversight over the course improvement projects. Both initiates fostered large volumes of published and publicly presented research.
The funding for course improvement projects through the ISTLD was non-competitive; the only requirements to receive a grant were to submit a draft proposal, to attend some workshops on pedagogy and to submit a new proposal guided by these workshops. Grants from the SEI at both UBC and CU was a competitive process, which Wieman used because, in his words, it was the only system familiar to science faculty.

In case you missed it, here is the first part of this book review, which discusses the content more directly.

Book review of Improving How Universities Teach Science, Part 1: Content.


Unlike many other books and literature on the subject, Carl Wieman’s Improving How Universities Teach Science - Lessons from the Science Education Initiative spent most of its pages talking about the administrative issues involving the improvement of university teaching. If you're familiar with recent pedagogical literature this book doesn't come with many surprises. What set it apart to me is the scale of the work that Wieman undertook, and his emphasis on educational improvement being an integrative process across an entire department rather than a set of independent advances.

 
The Science Education Initiative, or the SEI, model is about changing entire departments in large multi-year, multi-million dollar projects. The initiative focuses on transforming classes by getting faculty to buy into the idea of transforming them, rather than transforming the classes themselves directly.

The content is based on Wieman’s experience developing a science education initiative at both University of British Columbia (UBC) and at Colorado University (CU). It starts with a vision of what an ideal education system would look like any university mostly as an inspiring goal rather than any practical milestone. It continues with the description of how change was enacted in both of these universities. The primary workforce behind these changes was a new staff position called the science education specialist or SES. SES positions typically went to recent science PhD graduates of that had a particular interest in education. These specialists were hired and then trained in modern pedagogy and techniques to foster active learning. These specialists were assigned as consultants or partners to faculty that had requested help in course transformation.

 
The faculty themselves were induced to help through formal incentives like money for research, or through teaching buy-outs that allowed them more time to work on research, and through informal incentives like considering in teaching assignments and opportunities for co-authorship on scholarly research. Overcoming the already established incentive systems (e.g. publish or perish) that prioritized research over teaching was a common motif throughout this book.

 
The middle third of the book is reflective, and it’s also the meatiest part; if you’re short on time, read only Chapters 5, 6, and the coda.  Here, Wieman talks about which parts of the initiative worked immediately, which worked after changes, and which never worked and why. He talks about his change from a focus on changing courses to a focus on changing the attitudes of faculty. He talks about the differences in support he had at the different universities and how that affected the success of his program. For example, UBC got twice the financial support and direct leadership support from the dean. He also compares the success rate of different departments within the science faculty. Of particular interest to me are the UBC statistics and the UBC mathematics departments, which obtained radically different results. The statistics department almost unanimously transformed their courses, while the mathematics department almost unanimously didn’t.

 
Wieman also talks at length about ‘ownership’ of courses, and how faculty feeling that they own certain courses is a roadblock. Calling it a roadblock is partly because of the habit of faculty to keep their lecture notes to themselves on the assumption that they are the only one teaching a particular course. Furthermore, the culture of ownership was perceived to contribute to resistance from faculty to changes to their courses.

 
Under Wieman's model, course material is to be shared with the whole department so that anyone teaching a particular course has access to all the relevant material that has been made for it by department. Although UBC managed to create a repository for course material, the onus on populating that repository the faculty and there were few people that actually contributed. However where this matters most in the introductory courses even partial sharing was enough because many people tend to teach those courses.

 
The final third of the book is a set of appendices which include examples of learning activities and strategies in transformed courses, guiding principles for instruction, and several short essays on educational habits and references to much of the other work that Wieman has done. It also includes a hiring guide with sample interview questions for possible Science Education specialists.

 
The book also includes coda, which is an 8 page executive summary of the first two parts of the book. The coda served as a good review also a nicely packaged chapter that could be shared with decision makers such as deans and faculty chairs. Decision makers are exactly who I would recommend this book to; it has an excellent amount of information for the time and effort it takes to digest.


I had a few other thoughts about this book that were set aside for the sake of flow. You can find them in the second part of this book review.

Tuesday, 19 September 2017

Advice on Selecting the Right Journal

When I try to get something published in a journal, it's for the prestige and implied proof of quality.
Otherwise, if I wanted to write something and get attention for the idea quickly, I could write a blog post like this.

As such, I aim for a balance between the perceived importance of the journal and the chance of acceptance.

(Updated March 2019 with a section on predatory journals)